bash
ls -lh ~/Share/group_exercises/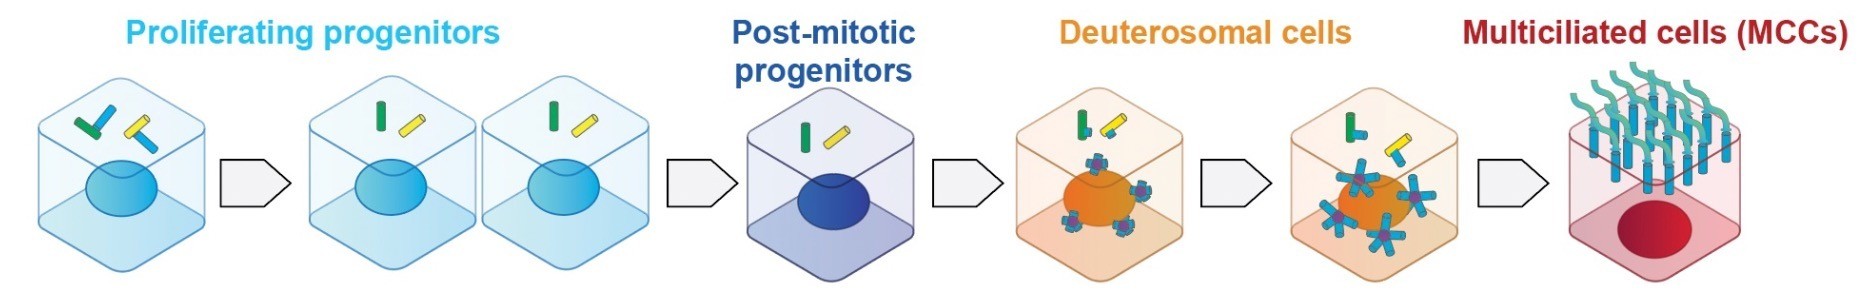
Multiciliated cells (MCCs) line the brain ventricles, the airways and the reproductive tracts: each of them grows dozens to hundreds of motile cilia, which beat to move fluids. MCCs differentiate from progenitors which exit the cell cycle, become post-mitotic, then amplify their centrioles (in deuterosomal cells) to template the motile cilia of mature MCCs.
Each group will analyse scRNA-seq datasets of the in vitro differentiation of mouse radial glial cell progenitors into multiciliated cells:
C57Bl6J and C57Bl6N);C57Bl6J background).The data is available in your session, in the ~/Share/group_exercises/ folder: for each dataset, a count matrix (*_counts.mtx.gz, in Matrix Market format), the genes (*_genes.tsv.gz) and the cells (*_barcodes.tsv.gz, with their sample, genetic background, total UMI counts and number of detected genes).
bash
ls -lh ~/Share/group_exercises/Import both datasets in R as SingleCellExperiment objects (this takes ~30 seconds and ~4 GB of memory):
R
library(SingleCellExperiment)
read_sample <- function(sample, dir = "~/Share/group_exercises") {
    counts <- Matrix::readMM(file.path(dir, paste0(sample, "_counts.mtx.gz")))
    genes <- readr::read_tsv(file.path(dir, paste0(sample, "_genes.tsv.gz")))
    cells <- readr::read_tsv(file.path(dir, paste0(sample, "_barcodes.tsv.gz")))
    sce <- SingleCellExperiment(
        assays = list(counts = as(counts, "CsparseMatrix")),
        rowData = genes,
        colData = cells
    )
    rownames(sce) <- rowData(sce)$ID
    ## The two WT replicates share some barcodes: prefix them with the
    ## sample and genetic background
    colnames(sce) <- paste(sce$sample, sce$background, sce$barcode, sep = "_")
    sce
}
WT <- read_sample("WT")
mutant <- read_sample("mutant")
WT
mutant
table(WT$background)Here is a checklist of the analysis steps we covered during the week. Not all of them will be relevant to your questions: decide which ones are, and why.
SingleCellExperiment object (Lab 3, Lab 4)Prepare a short presentation (10 minutes, max 5 slides), covering:
Groups who would rather analyse another dataset (e.g. from their own research, or from a paper they like) can do so: discuss it with the instructors first. The scRNAseq package distributes many processed datasets:
R
library(scRNAseq)
datasets <- surveyDatasets()
datasets
searchDatasets("pancreas")
sce <- fetchDataset("baron-pancreas-2016", "2023-12-14", path = "human")
The CZ CELLxGENE Discover and Human Cell Atlas portals, as well as GEO, are other good places to find processed count matrices.
These datasets were published in Khoury Damaa, Serizay et al., Cyclin O controls entry into the cell-cycle variant required for multiciliated cell differentiation, Cell Reports 2025 (GEO: GSE201773).